






AI servers explained
What is an AI server?
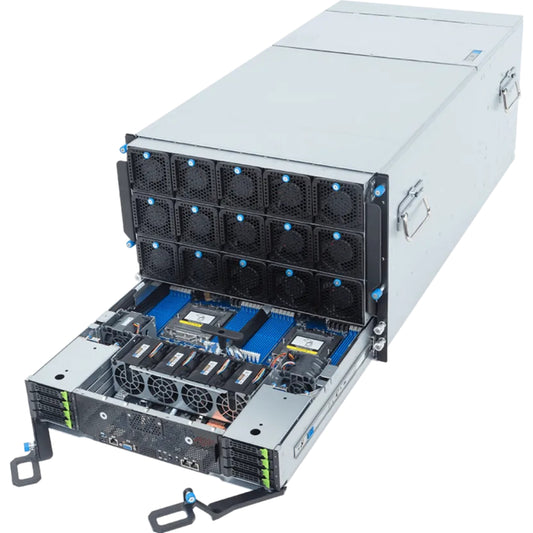
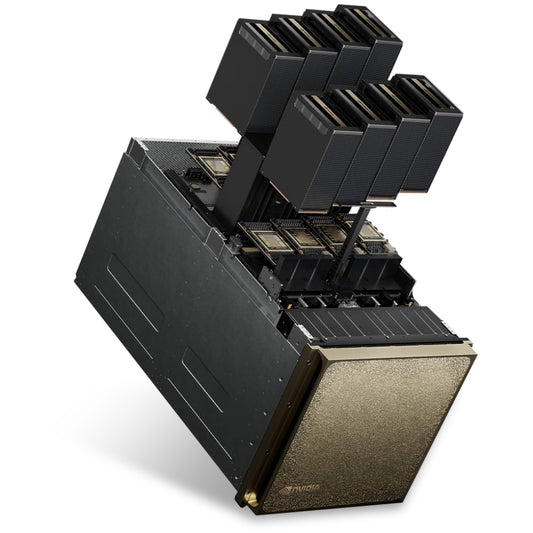
An AI server is a rackmount computer built to train and run AI models. A standard server is sized around its CPUs; an AI server is sized around its GPUs, usually four to eight in one chassis, each with its own high-bandwidth memory and linked by a fast interconnect so one large model can be spread across all of them. Rack-scale systems go further and join dozens of GPUs into a single rack.
Everything around the GPUs is scaled to keep them busy: server-class CPUs, large ECC memory, fast NVMe storage, high-speed networking to join several servers into a cluster, and power and cooling sized for kilowatts of continuous load.
- Serving an LLM to a whole team or to customers
- Fine-tuning open models on your own data
- RAG and search over internal documents
- Training models, vision and video analytics
Choose by tier
Three tiers of AI server
Each tier is a step up in GPU memory, in how the GPUs connect, and in the facility it needs. Pick the tier first, then the size.
4 to 8 GPUs over PCIe
RTX PRO 6000 Blackwell
96 GB of GDDR7 per GPU and up to 768 GB in one server. Suited to serving models to many users, RAG, embeddings and fine-tuning, where each model fits on one or a few GPUs.
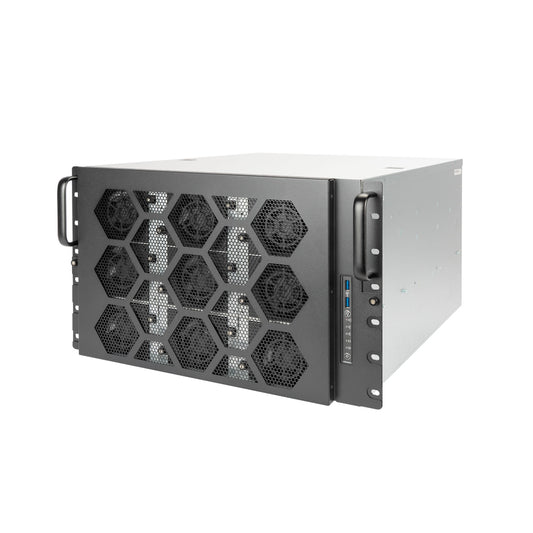
- EMARQUE AI PRO 500
Up to 4 GPUs, Threadripper PRO, 5U - EMARQUE AI PRO 700
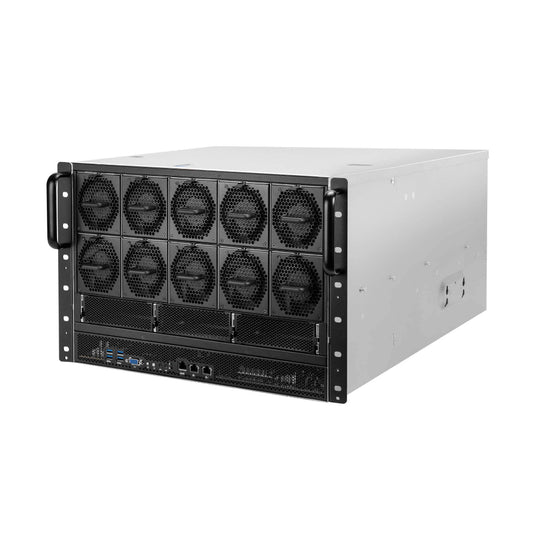
Up to 6 GPUs, 6.5U - EMARQUE AI PRO 800
Up to 8 GPUs, 6.5U
8 GPUs on NVLink
B300 Blackwell Ultra
Eight B300 GPUs on one NVLink baseboard with 2.1 TB of HBM3E, working as one large accelerator. Built for training and fine-tuning large models and for the highest-throughput inference.
- EMARQUE AI HGX B300 HGE8
8U, AMD EPYC or Intel Xeon - NVIDIA DGX B300
NVIDIA's own 10U system and software stack
Next generation
Rubin
NVIDIA's next GPU generation, with HBM4 memory and sixth-generation NVLink. Liquid-cooled, as an 8-GPU server or a full rack of 72 GPUs.
- EMARQUE AI HGX Rubin RGE8
8 Rubin GPUs, liquid-cooled - NVIDIA Vera Rubin NVL72
72 Rubin GPUs and 36 Vera CPUs per rack
Space, power and support
Where each AI server runs
The tiers differ as much in the room they need as in what they compute.
- Office server roomAI PRO 500, AI PRO 700
- Each runs from a single power supply of around 3 kW, so a 19-inch rack, good airflow and a dedicated power circuit are enough. No data centre needed.
- Server room with 3-phase powerAI PRO 800
- Eight GPUs on 9.6 kW of redundant power supplies. Plan for 3-phase power and a rack PDU sized for it.
- Data centre or colocationHGX B300 HGE8, DGX B300
- The DGX B300 draws up to around 14.5 kW in 10U. Both B300 systems need 3-phase rack power and data centre cooling.
- Liquid-cooled facilityHGX Rubin RGE8, Vera Rubin NVL72
- Rubin systems are liquid-cooled, and the NVL72 is a fully liquid-cooled rack. They need a facility with liquid-cooling infrastructure.
Owning the hardware keeps your models and data on systems you control, in Malaysia, and turns rented GPU hours into an asset you own. EMARQUE sizes the server to your workload, specifies the power, rack and networking, delivers and deploys it, and handles warranty and RMA locally.
FAQ
Questions, answered.
Straight answers on choosing, sizing, housing and buying an AI server in Malaysia, across the RTX PRO 6000 Blackwell, B300 and Rubin systems. Reviewed October 2026.
-
Is an AI server the same as a GPU server?
Close, but not quite. A GPU server is any server with GPUs in it, which can mean a single card for video transcoding, rendering or virtual desktops. An AI server is a GPU server built for AI work: several high-memory GPUs with a fast link between them, sized for training and serving models.
Every system on this page is both. If you are looking for a GPU server to train, fine-tune or serve AI models, these are the ones built for it.
-
How much GPU memory does my model need?
A useful rule of thumb: at 8-bit precision a model needs about 1 GB of GPU memory per billion parameters, plus headroom for context and concurrent users. At 16-bit, double it.
- A 70B model fits on one or two RTX PRO 6000 Blackwell GPUs, which have 96 GB each.
- A model of several hundred billion parameters needs the 768 GB of an AI PRO 800 or the 2.1 TB of a B300 server.
- Training the same model needs several times more memory than serving it.
EMARQUE sizes the server against your actual models, context length and number of users before you order.
-
RTX PRO 6000, B300 or Rubin: which platform should I choose?
RTX PRO 6000 Blackwell is the entry into multi-GPU AI. Each GPU has 96 GB of GDDR7 and the GPUs connect over PCIe, which suits serving models to many users, RAG, embeddings and fine-tuning where each model fits on one or a few GPUs.
B300 Blackwell Ultra puts eight GPUs on an NVLink baseboard with 2.1 TB of HBM3E, so they work as one large accelerator. Choose it for training and fine-tuning large models and for the highest-throughput inference. It comes two ways: the EMARQUE AI HGX B300 HGE8, where you choose the CPU, networking and storage, or the NVIDIA DGX B300, NVIDIA's own system with the DGX software stack, Mission Control and NVIDIA Enterprise Services.
Rubin is NVIDIA's next generation, with HBM4 memory and sixth-generation NVLink, as a liquid-cooled 8-GPU server or a full NVL72 rack. Choose it when your deployment date lines up with Rubin's production ramp and your facility supports liquid cooling.
-
AI PRO 500, 700 or 800: which one?
All three use NVIDIA RTX PRO 6000 Blackwell GPUs with 96 GB each, so the choice is GPU count, platform and power.
- AI PRO 500: up to 4 Workstation Edition GPUs (384 GB) with a 96-core AMD Threadripper PRO 9995WX, in a 5U SilverStone RM52 chassis on a single 3000W power supply. The simplest to house.
- AI PRO 700: up to 6 GPUs (576 GB) in a 6.5U In Win IW-RG650A with PCIe Gen4 slots, dual-socket Xeon or EPYC, on a single 3200W 80 PLUS Titanium supply. GPU count is scoped to that power envelope.
- AI PRO 800: up to 8 GPUs (768 GB) in a 6.5U In Win IW-RG658-PRO with PCIe Gen5, up to 8 TB of DDR5 and 9.6 kW of redundant power. The densest of the three, and the one that needs 3-phase power.
-
AI server, DGX Station or DGX Spark?
NVIDIA DGX Spark is a desktop AI computer with 128 GB of unified memory, for one developer prototyping, fine-tuning smaller models and running RAG. NVIDIA DGX Station is a deskside workstation on the GB300 Grace Blackwell Ultra Superchip with 748 GB of coherent memory, for a small team sharing one machine.
An AI server is the next step: rackmount, several GPUs per box, sized for many users or for training, and able to join other servers in a cluster. A common path is DGX Spark for development, DGX Station for a team, and an AI server once the workload becomes production infrastructure.
-
What rack space, power and cooling does each AI server need?
- AI PRO 500: 5U, single 3000W supply, air-cooled.
- AI PRO 700: 6.5U, single 3200W 80 PLUS Titanium supply, air-cooled.
- AI PRO 800: 6.5U, 9.6 kW of 3+1 redundant 80 PLUS Titanium supplies, air-cooled.
- EMARQUE AI HGX B300 HGE8: 8U, twelve 3000W redundant supplies, air-cooled, with liquid-cooled options on enquiry.
- NVIDIA DGX B300: 10U, up to around 14.5 kW from twelve 3.2 kW supplies, air-cooled.
- EMARQUE AI HGX Rubin RGE8: 2U to 3U depending on the cooling configuration, direct liquid cooling, 54 V DC bus-bar power.
- NVIDIA Vera Rubin NVL72: a complete, fully liquid-cooled rack.
EMARQUE specifies the rack, PDU, circuits and cooling for each system before delivery.
-
Can several AI servers be joined into a cluster?
Yes. The HGX B300 HGE8, DGX B300 and HGX Rubin RGE8 each carry eight 800 Gb/s ports through NVIDIA ConnectX-8 or ConnectX-9 SuperNICs, on InfiniBand or Ethernet, which is what lets several servers train one model together. The AI PRO 700 and 800 take ConnectX-class network cards for clustering and fast storage. Inside each B300 and Rubin server the GPUs share an NVLink baseboard, and the Vera Rubin NVL72 extends NVLink across the whole rack.
EMARQUE designs the network fabric, sets up the cluster and tunes it so the GPUs scale as expected.
-
What software comes with an AI server?
The NVIDIA DGX B300 ships with DGX OS, the NVIDIA AI Enterprise suite, Base Command and Mission Control, backed by NVIDIA Enterprise Services. The EMARQUE-built servers ship ready to run on Ubuntu LTS, or another Linux on request, with NVIDIA drivers and CUDA installed.
On those systems NVIDIA AI Enterprise, which adds NIM inference microservices and NVIDIA enterprise support, is a separate per-GPU licence. Open frameworks such as PyTorch and vLLM run without it. EMARQUE can also set up a private LLM, RAG or agent stack on request.
-
How do pricing and ordering work?
AI servers are priced by configuration: GPU count, CPU, memory, storage, networking, software licences and the deployment work around them. That is why the pages show no fixed price. Press ENQUIRE NOW on any server, or message the EMARQUE AI team on WhatsApp, and you receive a sized configuration, a quote and a delivery window.
Rubin systems are taken as pre-orders against EMARQUE's Malaysia allocation, so ordering early secures a place.
-
What does EMARQUE do beyond supplying the hardware?
EMARQUE is an AI server solution provider in Malaysia and has been building and deploying computing systems since 2016. The AI PRO servers are assembled, validated and stress-tested by EMARQUE in Malaysia and carry a 3-year EMARQUE warranty. For every system, EMARQUE sizes it against your workload, specifies power, rack and networking, delivers and deploys it, sets up clusters and private AI stacks, trains your team and handles warranty and RMA locally. Scope and charges are confirmed on enquiry. EMARQUE AI is the dedicated AI compute division behind this work.